s25061872.pdf - 第11页
Sensors 2025 , 25 , 1872 11 of 24 η t = η min + 1 2 ( η max − η min ) × ( 1 + cos ( T cu r T max π ) ) (18) where η t is the current learning rate. η min and η max are the minimum and maximum values of the learning rate,…
Sensors 2025, 25, 1872
10 of 24
X
i, m_2
(t + 1) = X
food
(t) ±C
3
×Temp ×rand ×
[
X
food
(t) − X
i, m
(t)
]
(13)
X
i, m_3
(t + 1) = X
i, m_3
(t) ±C
3
× F
m
×rand ×
h
Q × X
best, f
− X
i, m
(t)
i
(14)
X
i, m_4
(t + 1) = X
i, m_4
(t) ±C
3
× M
m
×rand ×
h
Q × X
i, f
(t) − X
i, m
(t)
i
(15)
where Q is the amount of food consumed. t denotes the current number of itera-
tions. T denotes the maximum number of iterations. Temp is the iteration temperature.
X
i
, m_1
, X
i
, m_
2
, X
i
, m_3
,
and X
i
, m_4
are the locations of food in the exploration phase of male
snakes, food in the development phase of male snakes, combat mode in the development
phase of male snakes, and mating mode in the development phase of male snakes, respec-
tively. X
rand
, m_1
is the randomly selected male population. X
best_f
is the best position for
the females in this population. A
m
, F
m
, and M
m
are measured for the male’s ability to find
food, the male’s ability to fight, and the male’s ability to mate.
Because the learning factors C
1
, C
2
, and C
3
remain unchanged during the iteration, the
algorithm may not adapt to the dynamic changes in the solution space. Hence, the delta
value is introduced for the normal distribution of random tubs. This perturbation helps
the SO algorithm eliminate the trap of local optimal solutions, thus enhancing its global
search abilities. In addition, the literature [
35
] introduces a learning strategy employed
within the ISO framework, which centers on acquiring knowledge from the experiences
of other group members. This approach aims to mitigate the likelihood of converging on
local optima. Nonetheless, the implementation of such specialized learning mechanisms
not only entails a notable increase in algorithmic complexity but also exhibits diminished
efficacy when adapting to the diverse phases of the optimization procedure. However, the
SO algorithm can achieve an effective dynamic balance between global and local searches
by dynamically adjusting these fixed learning factors C
1
, C
2
, and C
3
, thereby improving
the performance and efficiency of the algorithm. The concrete expression of the random
disturbance is shown in Equations (16) and (17). In Equation (19), alpha is used to store the
parameter values for learning factors C
1
, C
2
, and C
3
.
delta = sigma ×randn (16)
al pha(t + 1) = alpha(t) + delta (17)
where sigma represents the amplitude of the perturbation. It is 0.1 in this paper [
36
]. alpha is
limited to a range between 0.01 and 1. Random function ‘randn’ represents a random value
with a standard normal distribution.
2.4.3. Cosine Annealing Learning Rate
In Equations (12)–(15), the strategy for updating the individual positions is relatively
simple. Without considering adjusting the strategy as an iteration progress, the SO algo-
rithm mainly relies on the current individual’s position and velocity vector to determine
the next individual’s position. This method is more likely to cause the algorithm to become
stuck in a locally optimal solution. To improve the update strategy of the original SO
algorithm, this study introduced a cosine learning annealing rate. This strategy simulates
the dynamic adjustment of the learning rate based on the cosine function, which can dy-
namically adjust the speed of the position updating based on the number of iterations. In
the early stages of the iteration, the learning rate can be reduced rapidly to achieve fast
convergence. In the later stages of the iteration, fine adjustments are made to optimize the
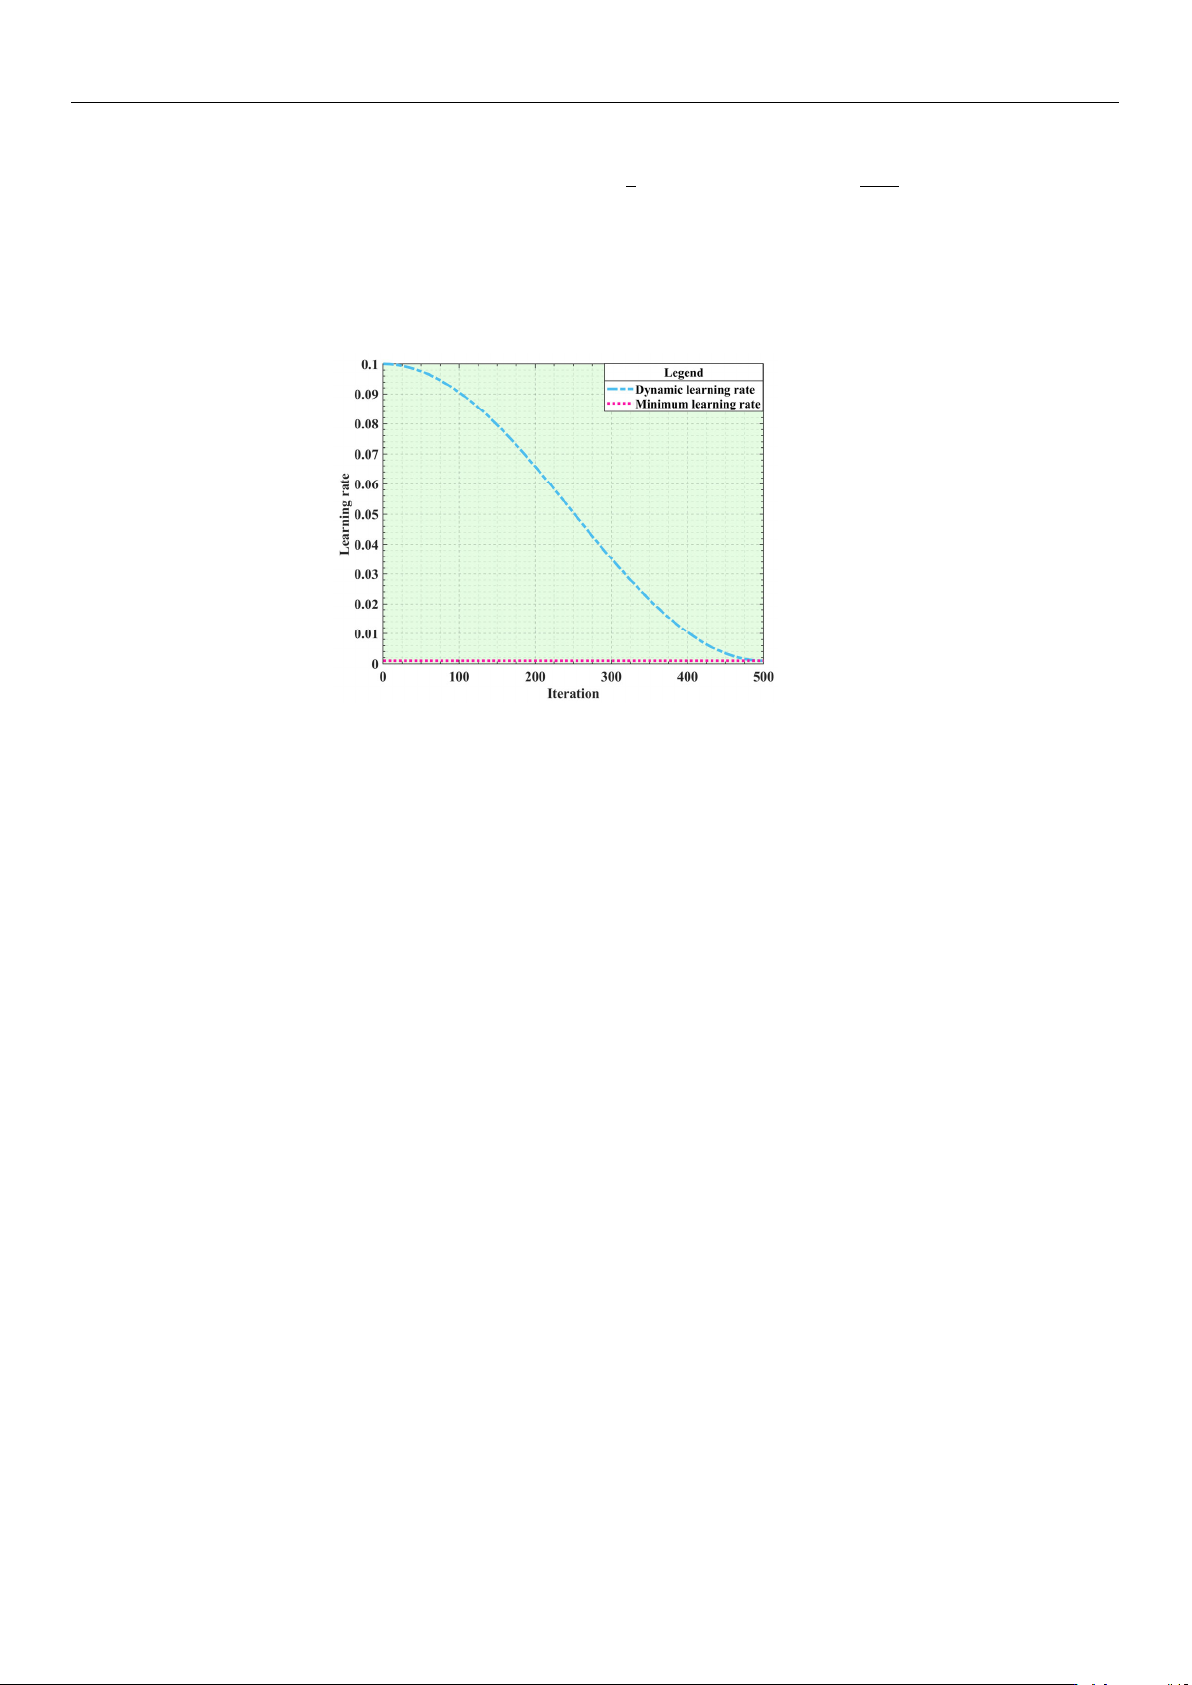
precision of the solution by reducing the learning rate, as shown in Figure 7. The specific
expression of the cosine learning annealing rate is shown in Equation (18).
Sensors 2025, 25, 1872
11 of 24
η
t
= η
min
+
1
2
(η
max
−η
min
) × (1 + cos(
T
cur
T
max
π)) (18)
where
η
t
is the current learning rate.
η
min
and
η
max
are the minimum and maximum values
of the learning rate, which are 0.001 and 0.01 in this paper. T
cur
and T
max
are the current
and total iterations, respectively. T
max
is usually set to half the number of iterations of the
main algorithm, which is 20 in this article [37].
Sensors2025,25,xFORPEERREVIEW 11 of 25
convergingonlocaloptima.Nonetheless,theimplementationofsuchspecializedlearn‐
ingmechanismsnotonlyentailsanotableincreaseinal gorithmiccomplexitybutalso
exhibitsdiminishedefficacywhenadaptingtothediversephasesoftheoptimizationpro‐
cedure.However,the SOalgorithmcan achieve aneffectivedynamicbalance
between
globalandlocalsearchesbydynamicallyadjustingthesefixedlearni ng factors C
1,C2,
andC
3,therebyimp rov in gtheperformanceandefficiencyofthealgorithm.Thecon‐
creteexpressionoftherandomdisturbanceisshowninEquations(16)and(17).InEqua‐
tion(19),alphaisusedtostoretheparametervaluesforlearningfactorsC
1,C2,andC3.
delta sigma randn
(16)
(1) ()alpha t alpha t delta
(17)
wheresigmarepresentstheamplitudeoftheperturbation.Itis0.1inthispaper[36].alpha
islimitedtoarangebetween0.01and1.Randomfunction‘randn’representsarandom
valuewithastandardnormaldistribution.
2.4.3.CosineAnnealingLearningRate
InEquations(12)–(15),thestrat egyforupdating
theindi vidualpositionsisrel‐
ativelysimple.Withoutconsideringadjustingthestrategyasaniterationprogress,theSO
algorithmmainlyreliesonthecurrentindividual’spositionandvelocityvectortodeter‐
minethenextindividual’sposition.Thismethodismorelikelytocausethealgorithmto
becomestuckina
locallyoptimalsolution.Toimprovetheupdatestrategyoftheoriginal
SOalgorithm,thisstudyintroducedacosinelearningannealingrate.Thisstrategysim‐
ulatesthedynamicadjustmentof thelearningratebasedonthecosinefunction,which
candynamicallyadjustthespeedofthepositionupdatingbasedonthenumber
ofitera‐
tions. In the early stages of the iteration, the learning rate can be reduced rapidly to
achievefastconvergence.Inthelaterstagesoftheiteration,fineadjustmentsaremadeto
optimizetheprecisionofthesolutionbyreducingthelearningrate,asshowninFigure7.
The
specificexpressionofthecosinelearningannealingrateisshown inEqua tion(18).
min max min
max
1
()(1cos())
2
cur
t
T
T
(18)
whereη
tisthecurrentlearningrate.ηminandηmaxaretheminimumandmaximumvalues
ofthelearningrate,whichare0.001and0.01inthispaper.T
curandTmaxarethecurrent
andtotaliterations,respectively.T
maxisusuallysettohalfthenumberofiterationsofthe
mainalgorithm,whichis20inthisarticle[37].
Figure 7. Cosine annealing learning rate iteration graph.
By comparison with the cosine annealing learning rate, Gaussian adaptive param-
eters [
38
] are sensitive to initial conditions, prone to premature convergence, and may
introduce additional computational complexity. However, the cosine annealing learning
rate exhibits periodic change, which enables the SO algorithm to adopt diverse search strate-
gies in different stages, thus enhancing the dynamic adjustment ability of the algorithm.
This flexibility helps the algorithm to avoid premature convergence during the search pro-
cess, thereby increasing the possibility of finding a global optimal solution. Therefore, by
introducing the cosine annealing learning rate based on Equations (12)–(15), the improved
Equations (19)–(22) are obtained.
X
i, m_1
(t + 1) = η
t
× X
rand, m_1
(t) ± η
t
×C
2
× A
m
×
[
(ub − lb) ×rand + lb
]
(19)
X
i, m_2
(t + 1) = η
t
× X
food
(t) ± η
t
×C
3
×Temp ×rand ×
[
X
food
(t) − X
i, m
(t)
]
(20)
X
i, m_3
(t + 1) = η
t
× X
i, m_3
(t) ± η
t
×C
3
× F
m
×rand ×
h
Q × X
best, f
− X
i, m
(t)
i
(21)
X
i, m_3
(t + 1) = η
t
× X
i, m_3
(t) ± η
t
×C
3
× F
m
×rand ×
h
Q × X
best, f
− X
i, m
(t)
i
(22)
2.4.4. The Bayesian Method to Find the Optimization Threshold
Bayesian optimization can be applied not only to neural network architectures based
on snake algorithms to improve system performance [
39
], but also to optimize hyperpa-
rameter combinations in machine learning. In the process of determining threshold values
of the SO algorithm, parameter setting often depends on the experience and intuition
of algorithm developers or needs to be determined by practical users through practice.
This approach lacks universality and requires considerable time for experimentation and
adjustments. If the parameters are not selected properly, the adaptability of the algorithm
may be affected. To solve the problem in which the SO algorithm has difficulty adapting
parameters in the iterative process, this study introduces a hyperparameter-tuning method
Sensors 2025, 25, 1872
12 of 24
commonly used in machine learning, which is known as Bayesian optimization. The
Gaussian process mainly includes Gaussian process regression and an acquisition function.
First, it establishes prior knowledge of the global behavior of the objective function
through a Gaussian process. The mean vector and covariance matrix involved in the
prior distribution are shown in Equations (23) and (24). Subsequently, using the observed
objective function to obtain values at different input points, this prior knowledge is up-
dated to form a posterior distribution. The posterior mean and variance are given by
Equations (25) and (26).
Then, the improved collection function is expected to consider
the current best observations and the posterior distribution of the Gaussian process to
determine the next evaluation point. The collection function used in this study is expected
to improve equation shown in (27). In short, this method of guiding the search based on
existing knowledge can avoid many useless attempts.
µ
0
=
[
µ
0
(x
1
), . . . , µ
0
(x
k
)
]
T
(23)
∑
0
=
∑
0
(x
1
, x
1
) ···
∑
0
(x
1
, x
k
)
.
.
.
.
.
.
.
.
.
∑
0
(x
k
, x
1
) ···
∑
0
(x
k
, x
k
)
(24)
We assume that the above expression follows a multi-variate normal distribution,
where
µ
0
(x) represents the mean function.
∑
0
(x,x’) represents the kernel function, also
known as the covariance function, which describes the similarity between points x and x’
in the input space.
µ
n
(x) = µ
0
(x) +
∑
0
(x, x
1
: n) ×(K
x
1
:n,x
1
:n
+ σ
2
I)
−1
×( f (x
1
: n) −µ
0
(x
1
: n)) (25)
σ
2
n
(x) =
∑
0
(x, x) −
∑
0
(x, x
1
: n) ×(K
x
1
:n,x
1
:n
+ σ
2
I)
−1
×
∑
0
(x
1
, n : x) (26)
EI(x) = E
[
max
(
f (x) − f
∗
, 0
)]
(27)
where K
x
1:n,x1:n
is the kernel matrix.
σ
2
is the noise variance. f (x
1
:n) is the observed vector.
f * = max
i
= 1, . . . n is the currently observed best target value. f (x
i
) is the function value.
This study uses the ‘bayesopt’ function in MATLAB 2022B, which is an easy to use
and flexible Bayesian optimization tool. With the help of this tool, three key threshold
parameters (food threshold, temperature threshold and mating threshold) that affect the
balance between exploration and development in SO algorithm are mainly optimized. The
original parameter settings are 0.25, 0.6, and 0.6, respectively. Under an integrated Bayesian
optimization framework, they are redefined as three adjustable variables: threshold
1
,
threshold
2
, and threshold
3
. The construction of the parameter space is based on the original
thresholds, extending
±
0.2 on both sides, ensuring the validity of the parameters while
avoiding the computational burden caused by an overly large search space. Consider-
ing the characteristics of the low-dimensional parameter space, a Bayesian optimization
configuration with a maximum of 10 iterations is adopted in this study, which not only
guarantees optimization efficiency but also effectively saves computational resources.
The method establishes a cooperative mechanism between Bayesian optimization
framework based on Gaussian process and SO objective function, and realizes intelligent
optimization of optimal threshold combinations through parameter search strategy guided
by this model. To improve parameter generalization, K-fold cross-validation is employed
for robustness assessment. This approach partitions the dataset into K subsets, analyzing
performance variations across these subsets to effectively prevent overfitting and guide
optimization toward parameter configurations with enhanced generalization capabilities.
This safeguard mechanism not only enhances the reliability of parameter optimization