743844-015.pdf - 第53页
The GNA is used to process speech recognition without user training sequence. The GNA is designed to unload the processor cores and the system memory with complex speech recognition tasks and improve the speech recogniti…
• Increased range of processor addressability in x2APIC mode:
— Physical xAPIC ID field increases from 8 bits to 32 bits, allowing for interrupt
processor addressability up to 4G-1 processors in physical destination mode. A
processor implementation of x2APIC architecture can support fewer than 32-
bits in a software transparent fashion.
— Logical xAPIC ID field increases from 8 bits to 32 bits. The 32-bit logical
x2APIC ID is partitioned into two sub-fields – a 16-bit cluster ID and a 16-bit
logical ID within the cluster. Consequently, ((2^20) - 16) processors can be
addressed in logical destination mode. Processor implementations can support
fewer than 16 bits in the cluster ID sub-field and logical ID sub-field in a
software agnostic fashion.
• More efficient MSR interface to access APIC registers:
— To enhance inter-processor and self-directed interrupt delivery as well as the
ability to virtualize the local APIC, the APIC register set can be accessed only
through MSR-based interfaces in x2APIC mode. The Memory Mapped IO
(MMIO) interface used by xAPIC is not supported in x2APIC mode.
• The semantics for accessing APIC registers have been revised to simplify the
programming of frequently-used APIC registers by system software. Specifically,
the software semantics for using the Interrupt Command Register (ICR) and End
Of Interrupt (EOI) registers have been modified to allow for more efficient delivery
and dispatching of interrupts.
• The x2APIC extensions are made available to system software by enabling the
local x2APIC unit in the “x2APIC” mode. To benefit from x2APIC capabilities, a new
operating system and a new BIOS are both needed, with special support for the
x2APIC mode.
• The x2APIC architecture provides backward compatibility to the xAPIC architecture
and forwards extensible for future Intel platform innovations.
NOTE
Intel
®
x2APIC Technology may not be available on all SKUs.
For more information, refer to the Intel
®
64 Architecture x2APIC Specification at
http://www.intel.com/products/processor/manuals/
Intel
®
Dynamic Tuning Technology
Intel
®
Dynamic Tuning (Intel
®
DTT) consists of a set of software drivers and
applications that allow a system manufacturer to optimize system performance and
usability by:
• Dynamically optimize turbo settings of IA processors, power and thermal states of
the platform for optimal performance
• Dynamically adjust the processor’s peak power based on the current power
delivery capability for optimal system usability
• Dynamically mitigate radio frequency interference for better RF throughput.
Intel
®
GMM and Neural Network Accelerator
GNA stands for Gaussian Mixture Model and Neural Network Accelerator.
2.4.14
2.4.15
R
Intel
®
Core
™
, Xeon
™
6300 And Xeon
™
E 2400 Processors—Technologies
13
th
Generation Intel
®
Core
™
, Intel
®
Core
™
14
th
Generation, Intel
®
Core
™
Processor (Series 1) and (Series 2), Intel
®
Xeon
™
E
2400 Processor and Intel
®
Xeon
™
6300 Processor
Datasheet, Volume 1 of 2 May 2025
52 Doc. No.: 743844, Rev.: 015
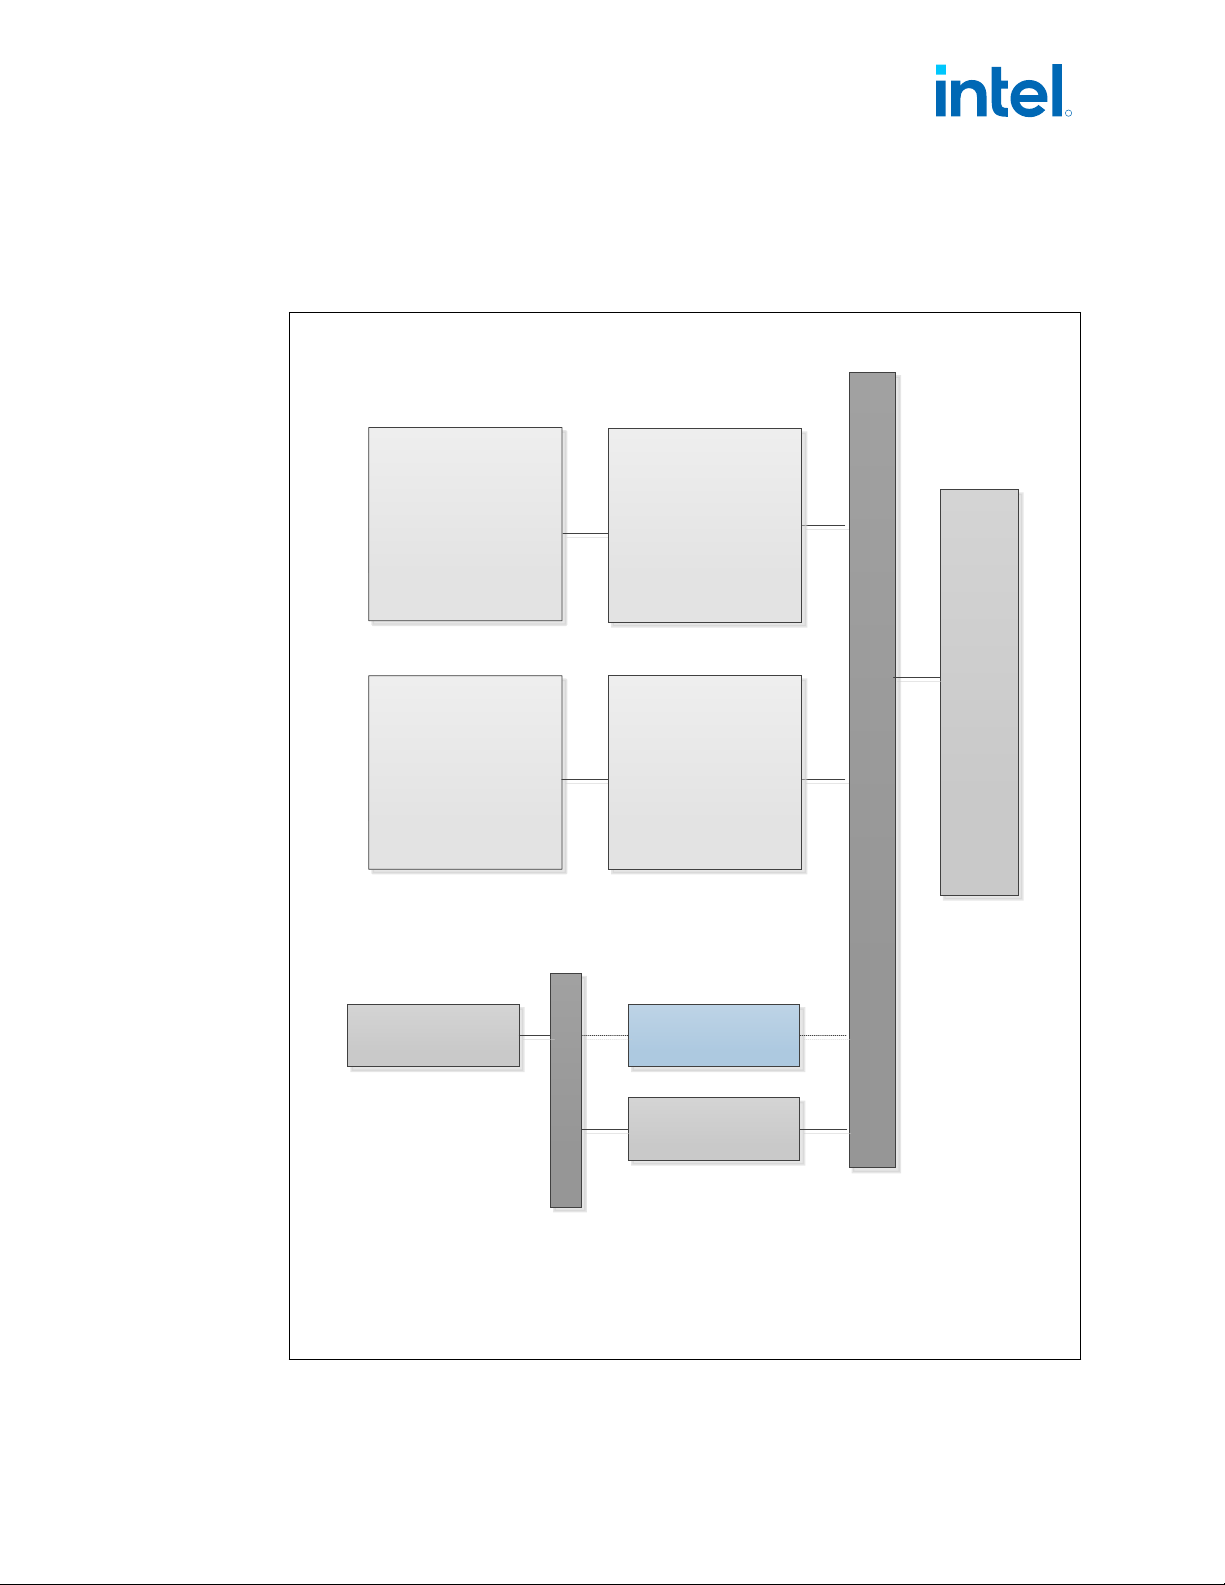
The GNA is used to process speech recognition without user training sequence. The
GNA is designed to unload the processor cores and the system memory with complex
speech recognition tasks and improve the speech recognition accuracy. The GNA is
designed to compute millions of Gaussian probability density functions per second
without loading the processor cores while maintaining low power consumption.
CPU
Core0
CPU
Core2
SRAM GNA
DSP
Memory Bus
DRAM
Memory Bus
CPU
Core3
CPU
Core1
R
Technologies—Intel
®
Core
™
, Xeon
™
6300 And Xeon
™
E 2400 Processors
13
th
Generation Intel
®
Core
™
, Intel
®
Core
™
14
th
Generation, Intel
®
Core
™
Processor (Series 1) and (Series 2), Intel
®
Xeon
™
E
2400 Processor and Intel
®
Xeon
™
6300 Processor
May 2025 Datasheet, Volume 1 of 2
Doc. No.: 743844, Rev.: 015 53
Cache Line Write Back
Writes back to memory the cache line (if dirty) that contains the linear address
specified with the memory operand from any level of the cache hierarchy in the cache
coherence domain. The line may be retained in the cache hierarchy in the non-
modified state. Retaining the line in the cache hierarchy is a performance optimization
(treated as a hint by hardware) to reduce the possibility of a cache miss on a
subsequent access. Hardware may choose to retain the line at any of the levels in the
cache hierarchy, and in some cases, may invalidate the line from the cache hierarchy.
The source operand is a byte memory location.
The Cache Line Write Back (CLWB) instruction is documented in the Intel
®
Architecture Instruction Set Extensions Programming Reference (future architectures):
https://software.intel.com/sites/default/files/managed/b4/3a/319433-024.pdf
Remote Action Request
Remote Action Request (RAR) enables a significant speed up of several inter-processor
operations by moving such operations from software (OS or application) to hardware.
The main feature is the speedup of TLB shootdowns.
A single RAR operation can invalidate multiple memory pages in the TLB.
A TLB (Translation Lookaside Buffer) is a per-core cache that holds mappings from
virtual to physical addresses.
A TLB shootdown is the process of propagating a change in memory mapping (page
table entry) to all the cores.
RAR supports the following operations:
• Page Invalidation: imitates the operation of performing INVLPG instructions
corresponding or the TLB invalidation corresponding with “MOV CR3 / CR0”
• Page Invalidation without CR3 Match: identical to “Page invalidation”, except
that the processor does not check for a CR3 match
• PCID Invalidation: imitates the operation of performing INVPCID instructions
• EPT Invalidation: imitates the operation of performing INVEPT instructions
• VPID Invalidation: imitates the operation of performing INVVPID instructions
• MSR Write: imitates the operation of WRMSR instructions on all cores
User Mode Wait Instructions
The UMONITOR and UMWAIT are user mode (Ring 3) instructions similar to the
supervisor mode (Ring 0) MONITOR/MWAIT instructions without the C-state
management capability.
TPAUSE us an enhanced PAUSE instruction.
The mnemonics for the three new instructions are:
• UMONITOR: operates just like MONITOR but allowed in all rings.
• UMWAIT: allowed in all rings, and no specification of target C-state.
2.4.16
2.4.17
2.4.18
R
Intel
®
Core
™
, Xeon
™
6300 And Xeon
™
E 2400 Processors—Technologies
13
th
Generation Intel
®
Core
™
, Intel
®
Core
™
14
th
Generation, Intel
®
Core
™
Processor (Series 1) and (Series 2), Intel
®
Xeon
™
E
2400 Processor and Intel
®
Xeon
™
6300 Processor
Datasheet, Volume 1 of 2 May 2025
54 Doc. No.: 743844, Rev.: 015